Data Governance Trends 2026
Why AI Governance Is an Engineering Problem, Not a Legal One
AI governance holds only if the data platform enforces the policy. What engineering-first governance looks like, and three questions before sign-off.
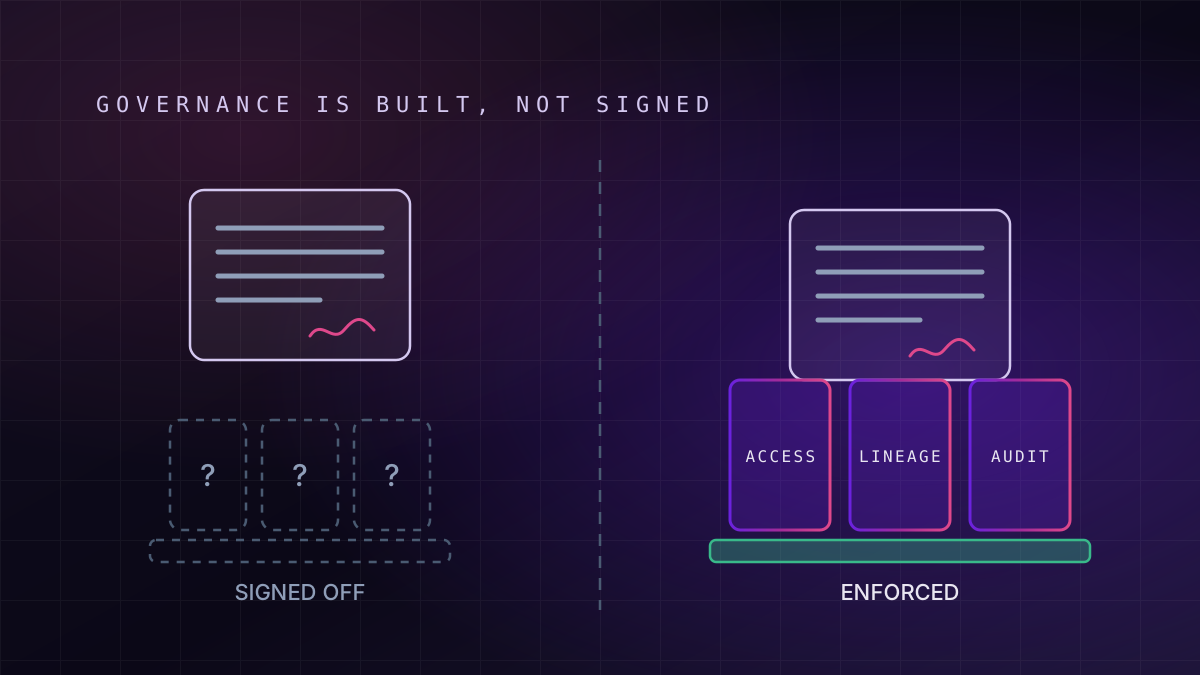
AI governance is an engineering problem because a policy holds only if the data platform enforces it. Enforcing it takes access controls the system applies, lineage from each AI output to its source data, and an auditable, correctable architecture. Gartner forecast in February 2025 that through 2026 organisations will abandon 60% of AI projects lacking AI-ready data.
Walk into most enterprise leadership meetings right now and you'll hear the same plan for AI governance. Someone drafts an ethics policy, legal reviews it, the board signs it, and that's taken as the job done.
Meanwhile the data pipeline feeding every model the company touches is exactly what it was before anyone wrote a word of that policy. It's still a patchwork of spreadsheets and half-documented databases, running on systems nobody fully trusts. A PDF won't stop a large language model hallucinating on sensitive client data, or an AI agent acting on a customer record that was wrong for six months before anyone noticed. Nor will it go back and build the access controls, lineage tracking and clean architecture that governance depends on.
A policy records what the company intends; the infrastructure underneath decides whether any of it happens.
In our reading, the research published since early 2025 keeps landing on the platform as the place where governance breaks, and the gap it finds is a common one.
What AI Governance Actually Means in an Enterprise
What this means for you: a control you can't show working in the system is really a rule you're trusting people to follow.
AI governance, in the sense that survives an audit, is the set of controls that decide what data an AI system can reach, how its outputs are traced and corrected, and who's allowed to change it, with the platform enforcing each one. The policy still matters. It says what the organisation intends and what it won't do, which makes it the specification; the controls are how that specification gets implemented.
People often use the term more loosely, for an ethics charter, a review committee or a risk register. Those all feed into governance, but none of them can stop a model reading a field it shouldn't see.
| Governance requirement | What a policy can state | What has to be built | Who builds it | Failure mode if it is only written down |
|---|---|---|---|---|
| Sensitive data stays restricted | Only authorised roles may use personal data in AI | Field-level access controls tied to identity, enforced at query time | Data platform engineering | A retrieval step returns a field nobody meant to expose, and nothing records that it did |
| Outputs are explainable | AI outputs must be traceable to their inputs | Data lineage from source to model input to output | Data engineering | Nobody can say which records shaped a decision once it is challenged |
| Data is fit for purpose | Models use accurate, current data | Quality rules and freshness checks that block bad loads | Data engineering | A model is retrained on a broken feed and the error looks like model drift |
| Changes are controlled | Changes to AI systems are reviewed | Versioned pipelines, prompts and models, gated in deployment | Platform and ML engineering | A silent change ships, and the audit trail starts after it |
| Errors can be corrected | Incorrect outputs will be remediated | An architecture that can find and reprocess affected records | Data architecture | Correction becomes a six-month project, so it does not happen |
The Numbers Behind the Gap
What this means for you: the organisations stalling on AI have their policies; what they lack is the data infrastructure those policies assume.
Gartner's February 2025 forecast is that through 2026, organisations will abandon 60% of AI projects that aren't supported by AI-ready data. Gartner's survey of 1,203 data management leaders, conducted in July 2024, found that 63% of organisations either don't have the right data management practices for AI or are unsure whether they do. That's close to two in three.
Redgate's 2026 State of the Database Landscape Report: AI Edition, published in June 2026, found that only 23% of firms use formal data governance or quality frameworks to manage fast-scaling environments. Redgate's 2026 report also found that 36% of enterprises manage four or more database platforms. Lineage has to be tracked and access enforced on each of those platforms separately, and any platform where that doesn't happen becomes a blind spot.
Agentic AI hits the same wall, sooner
Agents raise the stakes because they act on a company's behalf as well as answering questions; the agentic AI readiness framework covers what that demands. A Harvard Business Review Analytic Services survey of 603 technology decision-makers, fielded in July 2025 and published in December 2025, found that 9% of organisations had fully deployed agentic AI and only 6% fully trusted AI agents to run core business processes.
Readiness in the same HBR Analytic Services survey (2025) was lower than appetite: 20% said their technology infrastructure was fully ready for agentic AI in core processes and 15% said the same of their data and systems, while 12% said their risk and governance controls were fully ready.

Gartner's June 2025 forecast is that more than 40% of agentic AI projects will be cancelled by the end of 2027, citing escalating costs, unclear business value or inadequate risk controls. In our view, that third reason is a governance failure by definition, and an engineering one too, because the risk controls an agent needs are permissions, limits, logs and a way to stop it.
Key idea
The gap sits underneath the policy
We read these studies as pointing to one shortfall: data that isn't ready and controls that aren't in place, across estates too fragmented to track. Closing it is work for the people who build the platform.
Why Governance Keeps Getting Filed Under Legal
What this means for you: hand governance to the function that writes the rules and you've handed it to the function least able to make them true.
It's an understandable mistake. Ethics, bias and responsible use do have legal and regulatory sides, and legal teams are right to be in the room. The EU AI Act places duties on deployers. Since 5 February 2026, UK GDPR Articles 22A to 22D, introduced by the Data (Use and Access) Act 2025, permit significant automated decisions only with safeguards. Working out what those instruments require is legal work.
Building what they require is a different job. A legal team can write a policy saying customer data must be used responsibly and AI outputs must be explainable. It can't change how that data is stored or tag who has access to which field. Nor can it trace where a given number in a report actually came from, or rebuild a monolithic legacy system so that it supports clean, auditable access in the first place.
So the work falls between two teams. Legal owns the document and can't change the platform. Engineering owns the platform, and nobody told it the document had created work. The policy gets signed while the backlog stays exactly as it was, and the first anyone hears of the difference is an incident.
Failure mode
A signed policy with no backlog behind it
In our engagements, the commonest failure is a signed policy whose every requirement maps to engineering work that was never scoped, funded or assigned. The organisation believes it's governed while its systems carry on as if it weren't.
The operating model that turns the EU AI Act into named owners and gates exists to close exactly that gap. It only works if somebody builds the gates.
What Engineering-First Governance Looks Like
What this means for you: each line of the policy should map to a control you can point at in the platform, with an owner and a test.
Engineering-first governance, as we use the term, means designing each control into the data platform before an AI system goes live, so every clause in the policy has a control enforcing it, an owner and a test. That holds whichever cloud or platform the data runs on, whether it's Google Cloud, Microsoft Azure or Palantir Foundry. The tooling differs from one to the next, but the same things have to exist. In a real engagement, engineering-first governance comes down to three things.
Access enforced by the system
Granular, identity-based controls applied where data is queried and retrieved, so a model or agent can reach only what the person it serves is entitled to see.
Lineage from output to source
For every output a model or agent produces, a path you can follow back to the data that shaped it, so there's something to audit when an output goes wrong.
Architecture that survives change
Clean, modular layers that absorb a new model or a new regulation without a rebuild, so governance doesn't have to be re-engineered from scratch at every platform shift.
Controls that are code, not prose
If you want a rule to hold, make breaking it fail a build. Enforced in continuous integration, the rule no longer relies on anyone remembering it. Governance as code covers the mechanics: quality rules, access policies and lineage expectations written as version-controlled artefacts that pipelines enforce automatically.
Evidence the platform produces by default
A governed platform produces its own audit evidence just by running: access logs, lineage graphs, quality results and deployment history. That changes what an audit is. The quarterly exercise of reconstructing what probably happened turns into a query against what did. The evidence itself comes from the five disciplines that make a domain AI-ready, which are ownership, definition, lineage, classification and quality.

Why Sequencing Decides Whether Governance Holds
What this means for you: governance added after an AI system is live is a retrofit, and retrofits are where the cost and the gaps come from.
It's the same reason sequencing matters so much in any AI initiative. Think about what happens when an intelligent model or an autonomous agent is deployed on top of an ungoverned, poorly understood dataset.
On ungoverned data, the flaws already in it reach more decisions, faster, and the platform can't show how they got there.
We've made the case for repairing the data before layering AI on top in full elsewhere. Here the point is what it does to governance. Controls designed in before deployment shape the architecture. Bolt them on afterwards and they have to work around an architecture that was never built to carry them, and each workaround is a spot where the policy and the system quietly disagree. After go-live, continuous data observability is how you find out whether they still agree.
When Engineering-First Is the Wrong Frame
What this means for you: treat engineering-first as engineering-only and governance still fails, just for a different reason.
On one point Gartner's own research cuts the other way, and it deserves a straight answer. A Gartner survey of 223 data and analytics leaders, conducted in March 2026 and published that September, found that 60% of respondents cited cultural resistance as the primary reason governance initiatives fail, against 40% who cited funding constraints.
Gartner warns that many organisations stay focused on policy creation and technology enablement and overlook culture. Its advice is to treat governance as a responsibility shared between business and technology teams rather than an IT-only function.
That's a real limit on this argument. A platform can enforce a control, but it can't make a business team care whether the definition behind a field is right, and it can't keep an executive sponsor engaged after launch. Governance needs three owners, and losing any one of them makes it fail somewhere else. Business owners decide what the controls should protect and legal interprets what the law requires, while engineering builds the controls themselves.
In practice
Three names against every control
We write each control with three owners: the business owner who decides what it protects, the engineer who builds and runs it, and the legal reviewer who confirms it meets the requirement. When one of them is missing, the control tends to drift.
Heavy engineering can also come too early. A prototype on public or synthetic data, with no route to a customer and no decision attached, doesn't need a lineage platform, and building one before the use case has proved itself is its own kind of waste. What decides it is consequence. Once an AI system touches personal data, a customer or a decision about a person, its controls have to be running in the system itself.
Three Questions Before the AI Policy Is Signed Off
What this means for you: you can answer these in an afternoon, and the answers tell you whether the policy is protecting anyone yet.
Before anyone treats an AI ethics policy as the finish line, ask three questions that have nothing to do with the document. Put them to the people who run the platform, and ask for a live demonstration of each answer.
| Question | Evidence that answers yes | If the honest answer is no |
|---|---|---|
| Can you trace, with confidence, where the data behind a given AI output came from? | Pick a recent output and walk its lineage back to source records, live | Lineage is the first build item; until it exists, no output can be defended when challenged |
| Are access controls on sensitive data enforced by the system, or by people following a rule? | Attempt an out-of-role query through the AI path and watch it fail, with the attempt logged | Move the rule into the platform before the AI system widens its reach |
| Does the architecture support audit and correction without a six-month project? | Find every record a known-bad input affected, and show how it would be reprocessed | Scope the correction path now; an error you cannot reach is an error you will repeat |
If the honest answer to any of them is no, the ethics policy isn't protecting anyone yet, whatever it says.
What to do with the answers
- Turn every "no" into a backlog item with an owner and a date. A gap that only lives in a risk register isn't being fixed by anyone.
- Map each policy clause to the control that enforces it. A clause with no control behind it is either a build item or a sentence to remove.
- Have engineering and legal sign the policy together. Legal confirms it says what the law requires, and engineering confirms the platform can do what it says.
- Re-run the three questions at every major change, such as a new model, data source or agent permission. A check once a year can't tell you what the platform is enforcing today.
This is the work at the centre of our data architecture practice and our security and compliance work: taking the controls a policy assumes and making the platform enforce them. The same test of control decides whether a client still owns an AI system once its builder leaves.
Frequently Asked Questions
Is AI governance a legal responsibility or an engineering one?
Both, but they own different parts of it. Legal works out what regulation requires and drafts the policy that says so. Engineering builds the access controls, lineage, quality checks and audit trails that make the policy true in practice, and business owners decide what those controls protect. In our engagements, governance led only by legal tends to produce a signed policy with no engineering work behind it, and the systems behave as if the policy didn't exist.
What does engineering-first AI governance include?
In most enterprise estates it comes down to three things. Access controls tied to identity and enforced where data is queried, so a model or agent only reaches what it should. Data lineage from each AI output back to its source records, so a decision can be traced and challenged. Then a modular architecture that can find and reprocess affected records and take on a new model or regulation without being rebuilt from scratch.
Why do AI projects fail on governance rather than on the model?
In our experience, it's because the data underneath isn't ready, rather than because the model is weak. Gartner forecast in February 2025 that through 2026 organisations will abandon 60% of AI projects lacking AI-ready data, and its July 2024 survey found 63% of organisations without, or unsure of, the right data management practices for AI. Redgate's State of the Database Landscape Report: AI Edition (June 2026) found only 23% using formal data governance or quality frameworks to manage fast-scaling environments.
How can we test whether our AI governance is real?
Put three questions to the team that runs the platform, and ask them to demonstrate each answer. Can they trace a recent AI output back to its source data? Does an out-of-role query through the AI path fail, and get logged? Can they find and reprocess every record a known-bad input affected without a months-long project? Each "no" marks a control the policy names but the system doesn't have.
Does governance have to be built before an AI pilot starts?
Not for every pilot. A prototype on public or synthetic data, with no customer exposure and no decision attached, can run on lighter controls while the use case proves itself. What sets the threshold is consequence. Once a system touches personal data, a customer or a decision about a person, its access controls, lineage and correction path need to exist in the platform before it goes live.
Unolabs is a Data and AI first engineering consultancy, headquartered in the United Kingdom with engineering operations in Pune and active engagements across the UK, Australia, and Hong Kong. We help enterprises build the architectural foundation for autonomous AI execution — governed data platforms, semantic intelligence, and agentic systems that enterprises can stand behind.
If you are weighing where AI governance work should sit before your next deployment, book a discovery call and we will work through it with you.
More Where
This Came From.
New architectural deep-dives land every two weeks. Pick your channels and we will send them as they publish.
Continue reading
- Cloud Platform EngineeringGovernance as Code: Automating Data Quality in the CloudTurn data quality rules, access policies, and data contracts into version-controlled artefacts that CI/CD enforces before bad data reaches consumers.15 min read
- AI Readiness & StrategyThe AI Problem Nobody Talks About: It's the Data, Not the ModelEnterprise AI usually stalls on ungoverned data, not model choice. How to sequence the data foundation before the AI layer, and three cases where not to.13 min read
- Data Governance Trends 2026AI-Ready Data Foundations: The Governance Work That Comes FirstAI-ready data foundations decide whether models scale: quality at source, resolved entities, lineage to prediction, and inventories a regulator can audit.15 min read
Find out which of your AI controls exist only on paper
Bring one live AI system. We will test it against the three questions — lineage, enforced access, correctable architecture — and show which controls the policy names but the platform does not enforce.
Book a Governance Gap Review